What I set out to do
I enabled this a few weeks ago and started to log. I checked in on it this week (glad I did) and saw almost zero markdown hits except malware. I wanted to know whether any AI agents were actually requesting the markdown representation of the page, who they were, and how often - basically, is this worth keeping and optimizing, or is it a feature sitting there that nobody uses? I gave it 25 days to answer that.
How I checked it even works
Instead of testing an existing source, I triangulated:
- Edge tests (curl): confirmed
Accept: text/markdownreturns markdown. - Origin logs (SSH, nginx): measured AI-bot crawl volume by user-agent.
- Origin direct test: proved the origin only ever serves HTML, so the markdown conversion is 100% Cloudflare's edge, not the server.
- Cloudflare GraphQL Analytics: pulled the real edge content-type split and per-bot behavior.
- AI Crawl Control dashboard: cross-checked the feature status and fulfillment.
- I did not touch the server config - my network admin would kill me.
The feature works - and it is tiny
A GET with Accept: text/markdown returns content-type: text/markdown with a clean markdown body (YAML front-matter plus content), roughly 95% smaller than the HTML. AI Crawl Control reported "96% of markdown requests fulfilled."
What a markdown grab actually looks like
I wanted to see if what Cloudflare was outputting actually looked worthy of the page. I looked at a VDP (a vehicle page) because that is arguably the most important type of page on a car dealer. The highlights of what it grabbed:
- Title and description with the VIN baked into the description
- Basic info tables (Body: SUV, Mileage: 12,234, 21 hwy / 15 city MPG, Black/Black, 3.0L V6, ZF 8-speed)
- Full DESCRIPTION, DETAILS (the entire feature list - nav, harman/kardon, etc.), TERMS & CONDITIONS
- Price: $24,888.00, financing CTAs, VIN XYZ / STOCK MXYZ
- "Other vehicles you may like," full dealer NAP and hours
- It grabbed all the JSON-LD, which contains all the images of the car
- All of Yoast's output
Size: 23 KB markdown vs 369 KB HTML - about 16x smaller.
Does this actually matter for SEO?
When I started this I said: maybe, and probably. If LLMs can spend 96% less to get the exact same data, why wouldn't they? Twenty-five days later I have my answer, and it is no. Not today. The economics argument is sound and it did not matter even a little, because the crawlers are not making that decision on a per-request basis. They have a fetch pipeline that was written before any of this existed and it asks for HTML. Nobody at OpenAI or Anthropic or Perplexity is going to rewrite that because your edge would like to hand them something smaller.
I was wrong about the timeline. I figured a few of the big ones would be experimenting with it by now. Not one is.
Things I fixed and learned the hard way
- Vary: Accept was missing on HTML responses. Without it, caches can serve cached HTML to a markdown-negotiating client. Fixed with a Cloudflare Response Header Transform Rule (set static Vary = Accept-Encoding, Accept). This is what broke basically everything.
- Edge caching and markdown coexistence. Added a Cache Rule (HTML GET pages, 4h Edge TTL) that excludes
Accept: text/markdownand bots, so browsers get cached HTML (HIT) while agents still get freshly-converted markdown on the same URLs. I tested this several different ways. - The testing gotcha (this cost me a full hour):
curl -I(HEAD) returnstext/htmleven when the feature works, because HEAD has no body to convert. Always test with GET. A false "it broke" panic came entirely from using-I.
How I am logging it (and why I reset)
Version one was a homegrown Cloudflare Worker (a transparent passthrough) that logged every Accept: text/markdown GET to Workers Analytics Engine and fired a 30-minute Discord digest when there were hits. Here is what that looked like:
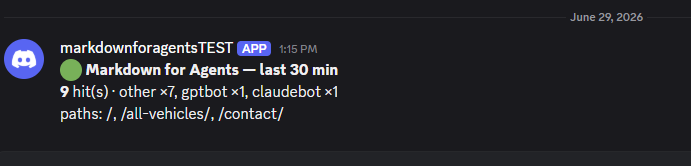
It did the job, but it was a moving part I had to babysit, and I let the logging get tangled enough that I stopped trusting the numbers. So I tore it out and switched to Cloudflare Log Explorer instead: raw, unsampled edge requests I query directly with SQL, including edgeresponsecontenttype, which flags a genuine markdown response so I can separate content-negotiated markdown from direct .md fetches in a single query. No Worker to maintain, no digest to babysit, and the data is straight off the edge rather than a sampled dashboard. It is a lot cleaner, which is why I reset the experiment to Day 1 on July 8 and ran the whole 25 days on Log Explorer. Every number in this post came out of one SQL query against that.
Why I am calling it a failure
I am closing this one out as a negative result, and I would rather publish that than let it sit as a "live experiment" quietly going nowhere for another two months.
To be clear about what failed. The feature is not broken. Cloudflare built it correctly, it converts cleanly, it fulfilled 96% of the requests it got, and the markdown it produces off a vehicle page is genuinely good - better structured than the HTML it came from. Every technical part of this worked. What failed is the premise: that if you serve markdown, agents will come take it. They did not. Twenty-five days, 2.78 million requests, and the entire named AI crawler population took it zero times.
The honest version of the finding is that markdown negotiation is not a distribution channel right now. It is a format that is ready before the readers are. If a vendor tells you turning this on will get you into AI answers, the log file says otherwise, and I have the log file.
Would I leave it on? Yeah. It costs nothing on Pro, it did not break caching once I got Vary right, and the day GPTBot flips it will already be there. But "leave it on and forget it" is a very different recommendation than what I was hoping to write, and I am not going to dress up 0 out of 121,824 as an early signal.
Two things I would actually spend time on instead, both of which came out of this run. First, if you are measuring bot behavior at all, verify by network, not user-agent - 54% of the markdown on this site went to a fake Googlebot and I would have booked it as adoption otherwise. Second, the six Claude-User pulls are the only part of this dataset pointing anywhere. Those are real people asking an assistant to go read a page in real time, and that path is small but it is not zero, which is more than the crawlers managed.
The post is closed but the daily Log Explorer pull keeps running, because the one thing actually worth catching is the day a big crawler flips from HTML to markdown. That is a five minute update to this page, not a new experiment. If ShapBot turns out to be somebody important in six months I will look stupid, and I will write that one up too.